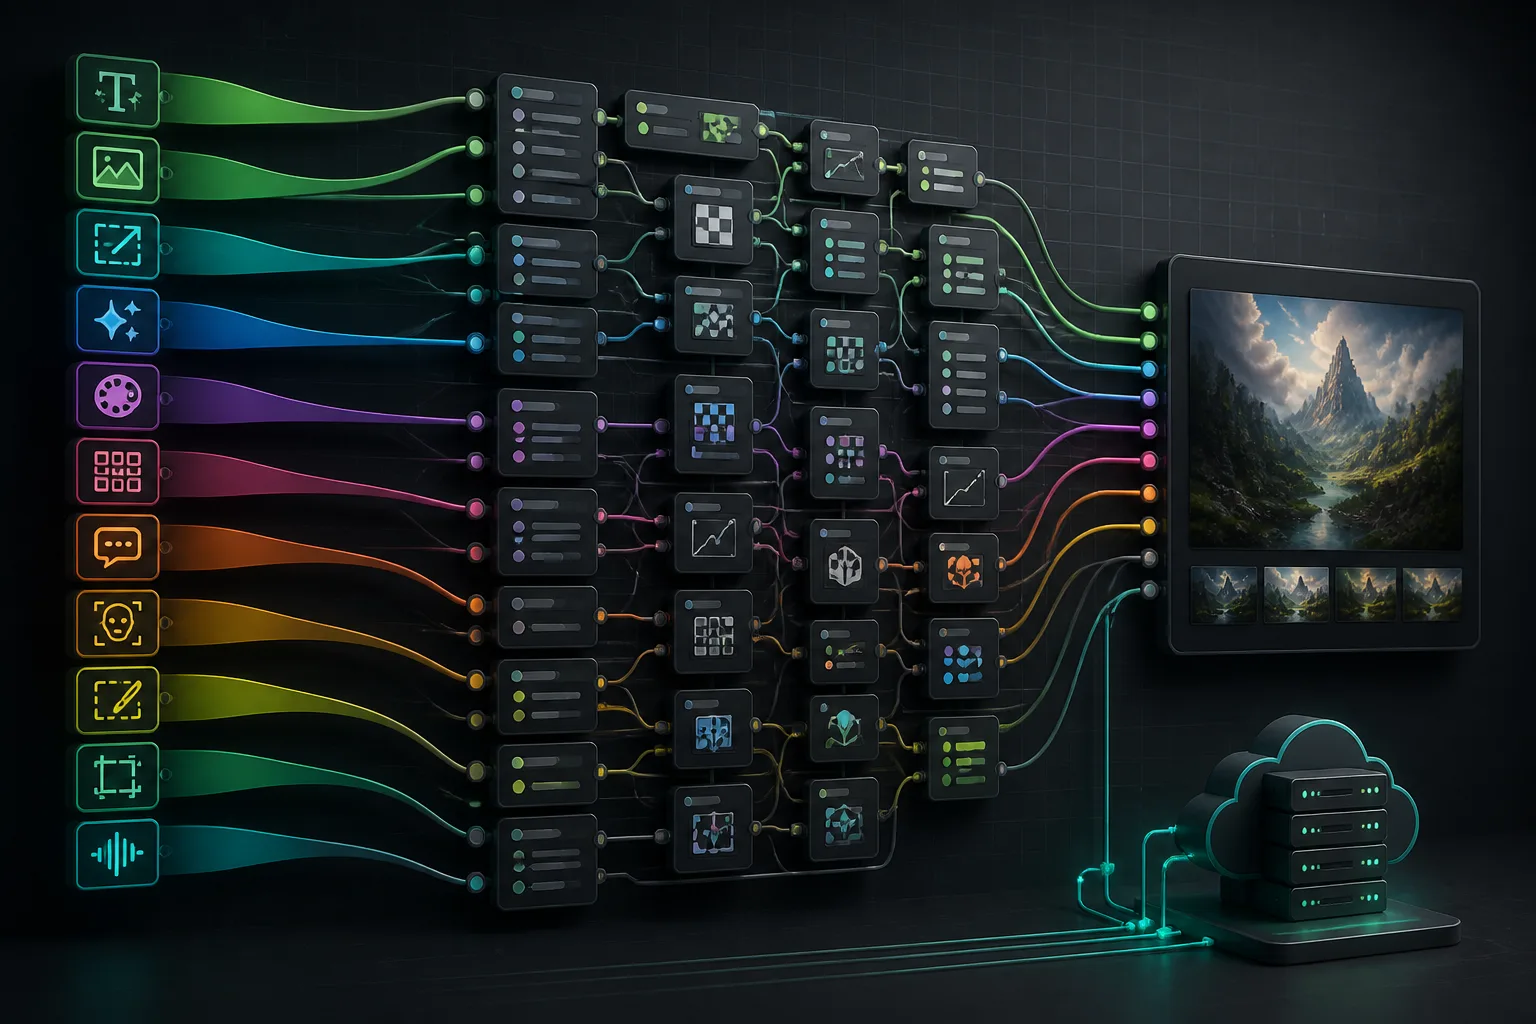
The authors present Workflow1111, a gr.Workflow canvas that consolidates most of AUTOMATIC1111’s feature set into a single graph. According to the post, the canvas contains eleven media pipelines implemented with seventy-three nodes and four operator kinds: fn, model, space, and dataset. Each node wraps one operator and exposes inputs and outputs as connectable ports.
Pipeline highlights
Text-to-image is described as the core pipeline and reproduces controls from AUTOMATIC1111’s txt2img tab: negative prompt, steps, CFG, seed, width, height and a model_id selector. A prompt-builder fn node appends style presets and cleans text before a model node calls the checkpoint through Inference Providers. A post-process fn writes generation parameters into PNG metadata, which the PNG Info pipeline later reads.
Other pipelines include a hi-resolution fix implemented as a refine call to a FLUX.1-Kontext model node; an image-to-image path that reuses the same Kontext node; and an LLM-driven prompt-expansion pipeline using Qwen3-4B. A VLM interrogate pipeline uses Qwen2.5-VL, while a ViT classifier returns percentage labels. Detection-to-inpaint converts DETR detections into masks and annotated images with local Pillow and NumPy code. Annotators equivalent to ControlNet preprocessors (Canny, line art, sketch, luma-depth, posterize) run as fn nodes, and the post notes that 36 operator nodes exist in the app, 32 are fn nodes and 22 of those run entirely in-process.
Integration, endpoints and local GPUs
Workflow1111 can call remote models through Inference Providers, invoke other Spaces (BRIA RMBG-2.0, AuraSR ×4) as space nodes, or load local checkpoints inside fn nodes. The authors explain that every output node becomes a REST endpoint; the post lists nine endpoints such as /image, /edited_image, /detected_objects and /png_info. Outputs can also appear as MCP tools for agents when launched with mcp_server=True.
The post gives examples of video and GPU usage: FastVideo/fastvideo-fasth3-preview runs a distilled FastH3 model under ZeroGPU, and a bound function can request a GPU at call time. Finally, the authors note that the canvas is editable in the browser, can be duplicated on the Hub, and that users can run pipelines by signing in with a Hugging Face account or providing an access token so model calls consume the caller’s quota.
Original source: Hugging Face Blog